High-Precision Transient Wave Recording Fault Indicator Supplier: What to Look for Before You Buy
2026-09-23
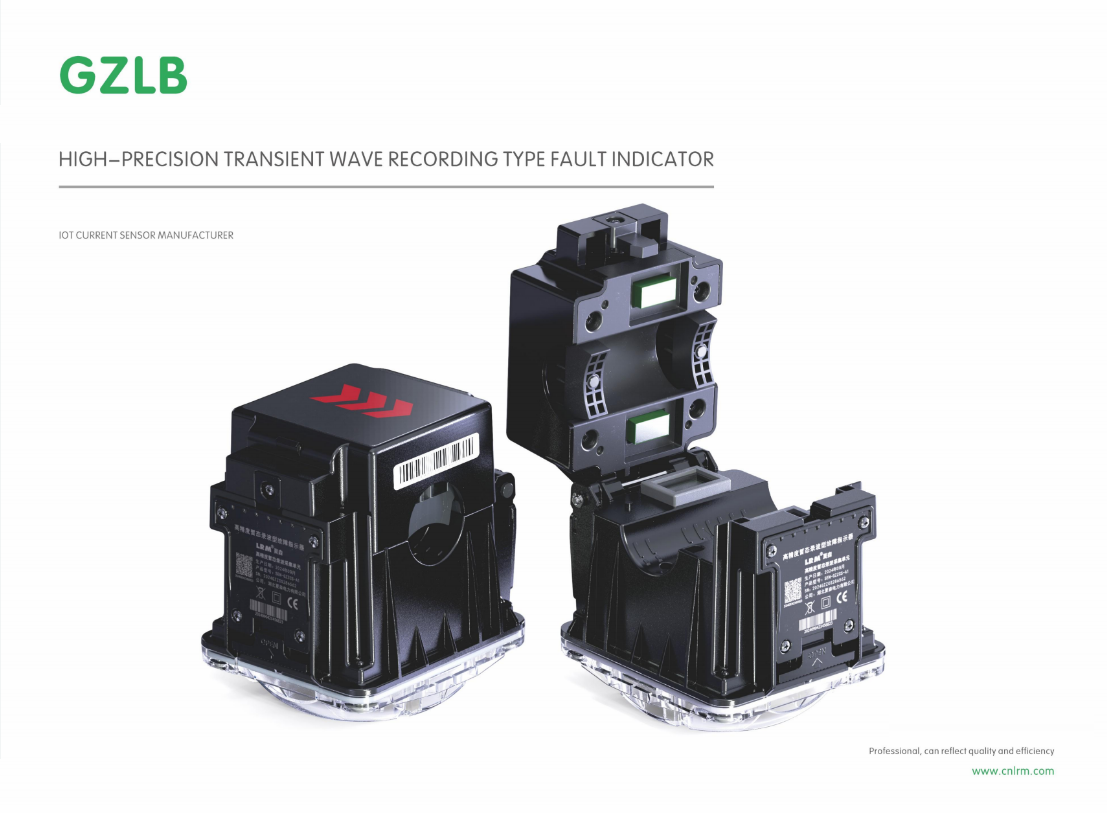
A fault indicator that misses a transient is just an expensive light bulb. If you're specifying high-precision transient wave recording fault indicators, you already know that sampling rate, trigger accuracy, and post-event analysis can make or break your grid diagnostics. But not every supplier delivers on those specs. Before you commit to a purchase, you need to look beyond the datasheet and ask hard questions about recording depth, waveform fidelity, and integration with your existing SCADA or protection schemes. One name that keeps coming up in those conversations is Xiasen, a supplier whose approach to transient recording has drawn attention from utilities tired of guesswork. In the sections ahead, we'll break down the factors that separate a genuinely reliable fault indicator from a box that just blinks red—and where Xiasen fits into that picture.
Can They Prove Accuracy on Real Faults, Not Just Catalog Numbers?
When evaluating any diagnostic or predictive tool, the first question should be: does it work on the messy, unpredictable faults that appear in the field, or only on the tidy, labeled examples from a benchmark catalog? Many systems boast high accuracy on curated datasets, where fault signatures are clean, well-separated, and preprocessed. But real machinery rarely fails so neatly. A gearbox seizure, an intermittent sensor dropout, or a hairline crack developing under variable load produces signals that drift, overlap, and carry noise. A vendor who cannot demonstrate performance on actual field failures—complete with the operational context, maintenance logs, and false-alarm rates—is asking you to trust a number that may not survive contact with your plant floor.
Look for evidence that goes beyond a single accuracy percentage. Ask to see case studies where the method was applied to previously unseen faults, preferably ones that were not part of the original training data. How many false positives did it generate per week? Did it catch the fault early enough for a planned shutdown, or only after the bearing had already seized? Real-world validation often involves long monitoring periods, multiple machine types, and changing operating conditions. A tool that fails to mention these details is likely hiding a brittle model that only shines in the lab.
The distinction matters because the cost of a missed fault or a false alarm is rarely symmetrical. A missed crack in a turbine blade can lead to catastrophic failure; too many false alarms will train operators to ignore the system entirely. Therefore, the proof must include the operational consequences, not just the confusion matrix. Demand field trials, third-party audits, and a clear description of how the system performed during unexpected events like load swings or maintenance interventions. If the vendor keeps pointing back to benchmark scores, you are looking at catalog accuracy, not real-world readiness.
What Happens When the Buffer Fills During a Long Outage?
During a prolonged outage, a device that keeps sensing or logging events will eventually hit the physical limit of its buffer. When that happens, the firmware has to make a hard choice. In many implementations, the buffer acts as a ring: once full, each new record overwrites the oldest one. This preserves the most recent data but silently erases the early part of the outage, leaving a gap that may only become visible after the connection returns.
Some systems take a different path and stop recording altogether until the network is back. That protects the stored records from being overwritten, but it creates a blind spot in monitoring. For industrial sensors or medical devices, losing visibility for hours or days can be worse than losing fine-grained history. A few designs try to stretch capacity by downsampling older entries, keeping coarse summaries while discarding raw detail.
The risk is even higher if the buffer lives in volatile memory. A power cycle during the outage can wipe everything before it is ever uploaded. That is why longer-lasting designs often pair a small RAM buffer with flash storage or an SD card. Ultimately, a full buffer during a long outage almost always forces a trade-off between data completeness, time coverage, and device uptime.
How Much History Do They Have with Utilities Like Yours?
A long track record can be comforting, but the real question is whether that history mirrors your own situation. A contractor might have twenty years in electrical distribution yet never touched a rural co-op with above-ground lines and frequent storm damage. Ask for specific examples that match your utility type, service area, and customer base, not just a generic list of years in operation.
Look for signs they have managed the full arc of a utility engagement: initial audits, regulatory hurdles, emergency repairs, and long-term maintenance cycles. Retention among existing clients can tell you a lot, but it can also hide inertia. Press for details on how they adapted when a similar utility faced a major outage, a compliance overhaul, or a sudden infrastructure failure.
History matters most when it is specific enough to predict their behavior in your circumstances. A firm that has spent fifteen years with investor-owned gas utilities may struggle with a small public water district's budget and reporting requirements. Weigh their past against the actual demands of your system, and do not let a polished timeline substitute for evidence of relevant work.
Will Their Support Team Actually Help You Decode the First Waveforms?
Getting a clear answer about waveform decoding from a support team often depends on the company behind the product. Some vendors staff their lines with engineers who have actually sat in front of a scope debugging a signal, so when you describe a strange rising edge or an unexpected ring after a trigger, they can walk you through possible causes instead of reading from a script. Others route you through a tier-one agent who only logs the ticket, and the real expertise arrives days later—if at all. That gap is what makes people skeptical.
A useful support interaction usually starts with specifics. If you send a raw capture, note the probe attenuation, sampling rate, and any bandwidth limiting you applied, the person on the other end has a much better chance of recognizing whether the first waveform is a true anomaly or a measurement artifact. In practice, many teams are willing to help with decode basics like setting thresholds or interpreting protocol frames, but they draw the line when you ask them to design your entire signal chain.
So the short answer is: yes, a good support team can help, but you have to meet them halfway. Prepare the exact conditions of your first capture, and ask focused questions about what you're seeing rather than expecting them to reverse-engineer your setup. If they respond with follow-up questions about your probing or grounding, that's usually a sign you're dealing with someone who can actually decode what's on screen.
Can the Data Flow Straight into Your Fault Analysis Software?
Fault analysis often stalls at the bridge between raw measurements and the software that crunches them. If your current workflow involves exporting CSV files, renaming columns, or copying numbers into a template, you already know the friction. The real question isn't whether your tool can import data—it's whether the data arrives in a shape your software actually expects, without a human babysitting every step.
Direct data flow means the recording device, the network drive, and the analysis engine all speak the same dialect. Voltage dips, harmonic snapshots, and event logs should land in the right fields the moment they're captured. When that pipeline is missing, engineers waste hours reformatting instead of investigating root causes. A few forward-thinking teams now use lightweight middleware that watches a folder, parses incoming files, and pushes clean records into the fault analysis database.
Ask your vendor one simple thing: "Show me a live feed, not a demo import." If the data can't flow straight in—unmodified, unprompted—then the software is just another manual step wearing a pretty interface. The best setups treat fault records like a stream, not a batch job you run at the end of the day.
Do They Offer Firmware Updates That Keep Old Units Useful?
A surprising number of manufacturers quietly drop support for older models within two years of release, leaving owners with hardware that still works but can't talk to newer apps or security protocols. The brands worth your money treat firmware as an ongoing responsibility, not a one-time launch task. Look for changelogs that mention fixes for units released five or more years ago—those are the companies that understand a device doesn't stop being useful just because a new version came out.
Some update cycles go beyond patching holes. A well-maintained firmware line can introduce features that didn't exist when the unit first shipped—think better battery management, support for newer Bluetooth codecs, or even entirely new operational modes unlocked via software. When a three-year-old unit suddenly gains a low-latency mode or expanded file format compatibility, that's a tangible return on your original purchase. Scour user forums for reports of “version 3.1 added X to my 2021 model”—those anecdotes tell you more than any marketing page.
The opposite experience is equally telling: a device that gets one token update six months after launch and then goes silent, even as obvious bugs pile up. That's a red flag the company treats hardware as disposable. A genuine long-term update strategy means the manufacturer has a dedicated team looking at legacy code, testing against new OS releases, and deciding what can be backported. If you can't find any evidence of that commitment—no changelog archive, no beta program, no response to older-model bug reports—assume your unit will become a paperweight sooner than you'd like.
FAQ
Data sheets often repeat the ADC chip's resolution, but the full signal chain matters more. Request raw COMTRADE files from actual faults on similar networks. If a supplier offers only lab-generated waveforms or refuses to share field captures, treat the precision claim as unverified. Also ask about their anti-aliasing filter cutoff and how they handle sensor saturation during close-in faults.
Look for at least five years of installed base on overhead and underground mixed feeders. More important than years is variety—ask for case studies where the indicator correctly identified high-impedance faults, intermittent arcing, or evolving faults. If all references come from one utility with a single conductor type, the device may not adapt to your conditions.
Yes, and it is often the weakest link. The hardware might capture excellent waveforms, but if the analysis software requires manual export, lacks batch reporting, or cannot overlay events from multiple units, engineers will stop using it. Ask for a trial license and load a week of your own disturbance data. Check whether the software automatically classifies fault type, phase, and distance, and whether it exports to standard formats without proprietary lock-in.
Do not accept a supplier that pushes only their own cloud portal. The indicator should support at least DNP3, Modbus TCP, and IEC 61850 for direct SCADA polling, plus a secure REST API for modern analytics platforms. Wireless options like NB-IoT or LoRaWAN are fine for low-power sites, but the device must also buffer data locally if communication drops for hours.
Ask the supplier to demonstrate inrush restraint and load current variation immunity. A good test is to replay recorded capacitor bank switching events and transformer energization. The device should only trigger on true fault signatures—such as di/dt polarity, zero-sequence current shifts, or transient energy above a configurable threshold. If the default settings rely on a fixed current pickup, you will get nuisance alarms.
Insist on firmware update commitment for at least ten years, with security patches released within 30 days of a disclosed vulnerability. The supplier should provide a named application engineer for the first six months and offer remote diagnostics via the device's own waveform export. Avoid contracts that charge per firmware update or require annual subscription just for basic settings changes.
Yes, especially for high-precision recording. Look at the cost of commissioning tools, calibration verification, data storage expansion, and cellular subscription fees. Some suppliers sell the indicator cheaply but charge for each waveform export or limit cloud storage to a few hundred events. Ask for a five-year total cost of ownership calculation, including battery replacement intervals and any required proprietary accessories.
Absolutely, and if the answer is 'no', move on. High-precision transient recording is useless if the trigger logic cannot be tuned to your fault signatures. A competent supplier will offer trade-off settings for pre-fault and post-fault duration, sampling rate drops after initial capture, and user-defined threshold curves. Request a configuration file from a similar project to see whether the parameters are editable by your team or locked behind factory-only software.
Conclusion
Before signing a purchase order, push the vendor for field evidence rather than polished spec sheets. Ask them to demonstrate how the high-precision transient wave recording fault indicator performed during actual line faults—tree contact, cable faults, lightning strikes—not just in a controlled lab. A supplier that can walk you through oscillography captured on a real feeder and explain the trigger timing, sampling rate, and waveform fidelity under noisy conditions is worth far more than one quoting theoretical accuracy. Equally important is what happens when the buffer fills during a prolonged outage. Some units simply overwrite the oldest records, silently discarding the very first transients that often hold the key to locating the fault. Others lock the buffer and stop recording until a crew retrieves the data, which can be worse if the outage lasts for hours. Ask for the exact memory management logic and test it with a simulated long-duration event. Also, check how long the supplier has worked with utilities of your size and voltage class. A company that has spent a decade supporting rural cooperatives or municipal systems will understand recloser coordination and communication constraints better than one whose main customers are industrial plants.
After the device is installed, the real test is whether the support team can read the first waveforms with you instead of filing a ticket. You want engineers who recognize a pre-fault voltage sag or an evolving arcing fault, not just script readers. Ask for a sample waveform capture from a recent utility event and see if they can annotate the key features before you buy. The data also needs to flow directly into your existing fault analysis software, not force you to export CSV files and rebuild records by hand. If the indicator talks only through a proprietary viewer, you are buying a data island. Confirm that it can export COMTRADE or at least a well-documented ASCII format your package imports without manual conversion. Finally, firmware updates matter more than most buyers realize. A supplier that has kept the same hardware platform alive for five or more years with regular feature additions—better trigger algorithms, communication protocol fixes, security patches—protects your budget. Ask to see the release history and whether older units actually receive the same updates, or only the newest model.
Contact Us
Contact Person: Liu Mengyang
Email: [email protected]
Tel/WhatsApp: 8618727589233
Website: https://www.cnlrm.com/en/