Digital Inkjet Marking System Makers: What Sets the Best Apart
2026-10-09
Choosing a digital inkjet marking system often starts with a spec sheet, but the real difference shows up months later—when printheads clog, software stalls, or support goes quiet. That’s why the maker behind the machine matters as much as the machine itself. In this post, we look at what separates the best digital inkjet marking system manufacturers from the rest, and why brands like Danmajet keep earning attention from production teams that can’t afford downtime.
Engineers Who Pick Up the Phone
An engineer who picks up the phone is a rare breed. For every one willing to talk to a frustrated customer mid-call, there are a dozen hiding behind ticketing queues and status updates. That reflex to avoid the live conversation is understandable — phone calls are messy, interruptions break flow, and the person on the other end rarely has a tidy bug report. But the ones who answer anyway tend to hear things no log file will ever show: the hesitation in a user’s voice, the workaround they didn’t mention, the exact word they use to describe a feature that isn’t working.
When engineers take calls directly, the loop between problem and fix shortens dramatically. A support ticket can sit for days with back-and-forth questions about environment or expected behavior. A five-minute phone call often replaces five rounds of email. The customer explains what they were trying to do, the engineer asks one or two pointed questions, and the root cause becomes obvious. It’s not about being on call all day; it’s about making direct contact a normal part of the workflow. Teams that do this tend to ship fixes that match the actual problem instead of the assumed one.
This habit doesn’t scale to every role, and forcing it on engineers who loathe it usually backfires. But a small rotation or a “talk to a user” hour can reshape how product decisions get made. Engineers who pick up the phone stop treating the product as an abstraction. They start remembering that behind every error code there’s a person trying to get something done. That shift in perspective often costs nothing more than a few awkward conversations — and it can be the difference between a team that builds features and one that solves problems.
Custom Formulations Without the Custom Price Tag
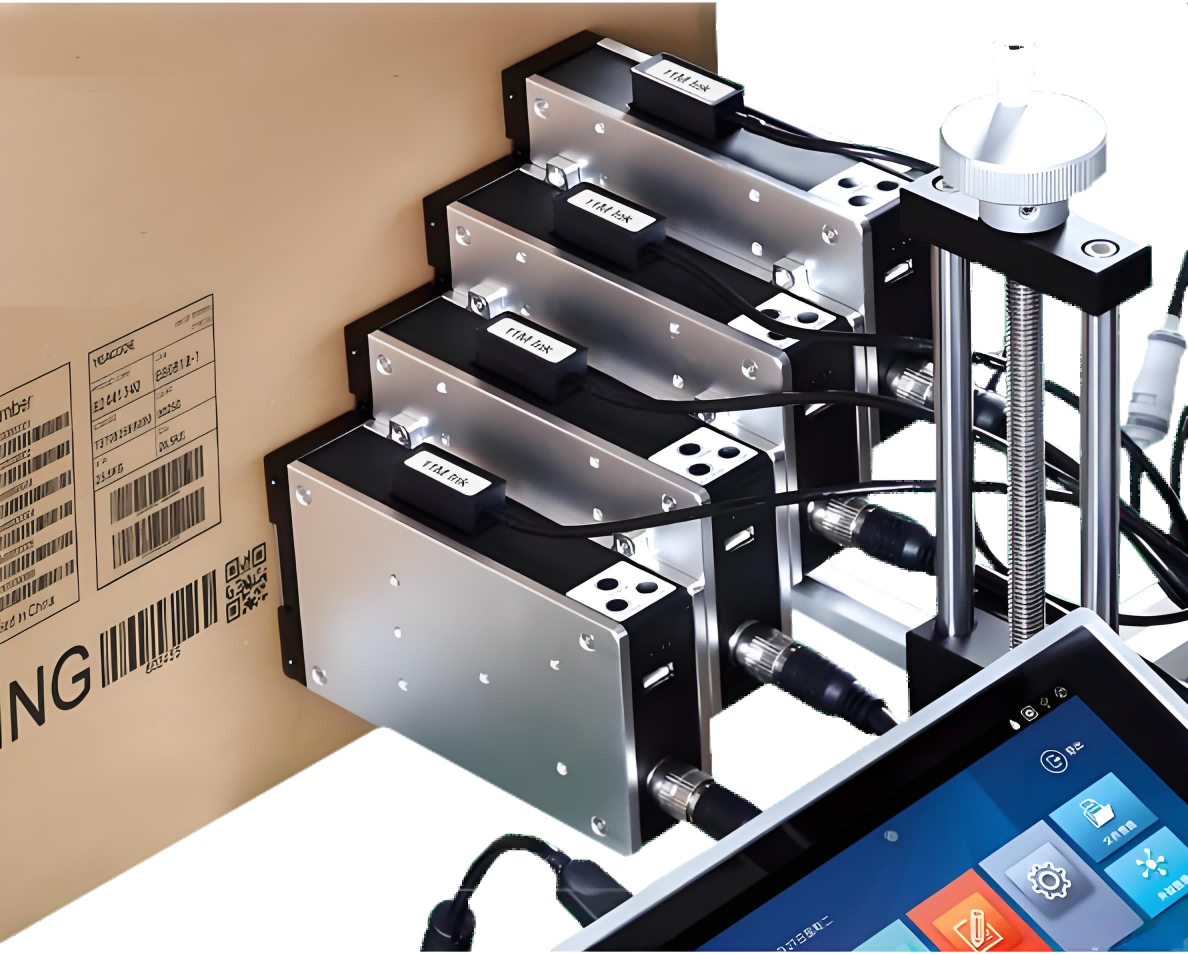
Most suppliers treat custom formulations as a luxury—charging steep setup fees, high minimums, and inflated per-unit costs. We flipped that model. By building on a flexible base of pre-tested ingredient systems, we can create a product that feels made-to-order for your brand without the typical price hike. You get the exact texture, scent, actives, and packaging compatibility you need, while paying closer to off-the-shelf rates.
The savings come from efficiency, not compromise. Instead of starting from scratch every time, our chemists adapt proven matrices to your specs. That means fewer development rounds, no wasted lab time, and zero charges for tweaks that should be standard. Whether you need a 500-unit trial run or a full production scale-up, the cost per unit stays predictable—and far below what boutique custom labs quote.
This approach lets you launch a distinctive product line without gambling your budget. You keep the margin you need to grow, and your customers get something that doesn't exist on any other shelf. No generic fillers, no premium markup—just a custom formula that finally fits the reality of your balance sheet.
Uptime Math in Every Design Choice
Reliability isn’t a bonus bolted on after launch—it’s the arithmetic running underneath every layout decision, every API call, every background job. When an engineer picks a primary database region, they’re silently multiplying possible failure windows. When a frontend caches a stale flag for five minutes instead of five seconds, they’re adding decimals to a downtime ledger most teams never read aloud.
The quiet truth of infrastructure design is that redundancy costs less than recovery. A load balancer configured with a short health-check interval sounds trivial until you calculate the difference between forty seconds of degraded traffic and three. Choosing idempotent retries over best-effort single writes isn’t just a style preference—it’s the difference between a spike erased and a spike amplified. Good uptime math hides in unglamorous places: connection pool sizes, timeout budgets, graceful shutdown sequences.
Teams that treat each design choice as a probability equation don’t ship faster by skipping checks; they ship calmer by knowing which failures are acceptable and which are not. The result is a system where a missing index is a lesson, not an incident, and where on-call pages arrive with context instead of panic. In the end, every added nine of availability comes from thousands of small multiplications, not a single heroic fix.
Plugging Into Your Line Without Rewriting SOPs
Adding a new piece of equipment to your production line usually triggers a cascade of paperwork, retraining sessions, and revised binders. It doesn't have to. The real trick is designing the integration to speak the language your operators already understand, not the other way around. Instead of rewriting every step, focus on mapping the new tool's inputs and outputs to the existing checkpoints and tolerances your crew has been hitting for years.
Think of it less like replacing a chapter and more like slipping a bookmark into a well-worn manual. The machine can be configured to present readings in the same units, flag exceptions using the same color codes, and log results into the same fields your quality team already reviews. That way, the daily routine barely shifts. Operators keep following the familiar flow, and the new capability sits quietly inside it, doing its job without demanding a ceremony.
Where you do need a small adjustment, keep it confined to the edge. Add a one-page quick reference card next to the station instead of overhauling the training module. Have the new system prepopulate the existing form rather than introducing a separate report. By treating the existing SOP as a constraint to design around, you get the productivity gain without the change-management migraine.
Preventive Support That Reads Production Data
Most support teams wait for a ticket to arrive before they look at anything. Preventive support works the other way around: it reads production logs, transaction patterns, and resource metrics as they happen, looking for drift before it becomes downtime. A query that suddenly takes three times longer than last Tuesday, a memory curve that stops flattening after deploys, a retry storm building in one service—these are the early signals that a reactive model misses.
The value shows up in the quiet fixes. Instead of paging a developer at 2 a.m., the system can roll back a bad config, shed load from an overheating queue, or spin up a replacement node based on what the production data already predicted. That kind of intervention doesn't need a human to triage first; it needs the data to be trusted enough to act on. The difference is not just faster response, but fewer incidents that ever reach a customer.
Industry-Specific Proof Instead of Broad Claims
Broad adjectives like 'best-in-class' or 'proven track record' stop meaning anything the moment a plant manager has to justify a purchase to finance. In heavy equipment, a supplier that claims 'superior durability' gets ignored; the supplier that shows a haul truck bucket lasting 900 hours longer in a copper mine in Arizona—with maintenance logs attached—gets the meeting. Industry-specific proof means replacing sweeping statements with evidence that matches the exact conditions your customer already lives in. It’s not about being impressive; it’s about being relevant enough to survive a skeptic’s cross-examination.
For a food processing line, proof doesn't look like a banner ad saying 'hygienic by design.' It looks like a third-party audit report showing zero critical findings across three consecutive years, plus a line supervisor’s note that the new conveyor’s open-frame design cut sanitation time from 40 minutes to 15 per shift. In financial services software, a vendor that says 'security is our priority' loses to one that hands over a penetration test with no high-severity findings and a reference from a mid-sized credit union where fraud disputes dropped 27% after implementation. These aren’t marketing blurbs; they’re operating data pulled from a specific industry’s daily reality.
When you replace broad claims with industry-specific proof, the sales conversation shifts from persuasion to verification. Instead of defending adjectives, you walk buyers through a scenario they recognize. A useful discipline: write every claim as 'for [specific type of customer] in [specific context], we delivered [measurable change].' If you can’t fill in the brackets with a real example, cut the claim. It forces you to gather stories from actual deployments—like the automotive supplier that cut die-change time from 50 minutes to 19 after adding quick-release clamps—rather than rehashing generic value propositions that every competitor already uses.
FAQ
It usually comes down to how well they handle variable data at production speed. The best makers design printheads and controllers together, so the system doesn't stutter when line speeds climb or codes change every few milliseconds.
More than most buyers realize. A maker that develops its own inks can guarantee adhesion on difficult substrates like film, glass, or metal. Generic inks often work fine on paper but fail quickly on curved or coated packaging.
Integration tends to create fewer daily headaches. A machine with slightly lower native resolution but clean ERP and database hooks will outperform a spec-sheet champion that requires manual coding for every job change.
It's huge. The best systems have automated nozzle checks, self-cleaning cycles, and sealed ink paths that prevent drying during short stoppages. Ask for uptime data from existing users before you buy.
If you run multiple product sizes, yes. Modular arrays let you scale print width without replacing the entire controller or software. They also isolate failures, so one damaged head doesn't shut down the whole line.
Physical proximity matters when a packaging line is down. Top makers train regional technicians and stock critical spare parts nearby. Remote support is fine for software bugs, but a clogged ink system needs hands-on service within hours.
Sometimes they can, especially in niche applications. Look for smaller firms that focus on one industry, like cable marking or pharmaceutical cartons. Their concentrated engineering effort often produces better results than a generalist's diluted R&D.
They focus only on print speed or DPI numbers and ignore environmental factors like dust, humidity, and temperature swings. A system that survives a clean factory may fail in a bakery or a foundry, so always test with your actual line conditions.
Conclusion
The best digital inkjet marking system makers stand apart through accessible engineering and practical customization. You aren't handed off to a call center; you reach the person who actually designed the printhead or wrote the firmware, which matters when a line goes down at 2 a.m. They also manage to offer custom ink formulations for odd substrates or curing requirements without charging a king's ransom—no bloated R&D fees, just a batch tweaked to your production reality. Underneath all that, every design decision is run through uptime math: how many seconds does a printhead swap take, can a nozzle clean itself mid-shift, is the ink system built to avoid sedimentation? These choices aren't marketing bullet points; they show up as fewer line stoppages and faster recovery.
Integration also separates top makers from the rest. The best systems drop into an existing packaging line without forcing operators to relearn everything; the interface mirrors current workflows, and the trigger, encoder, and reject signals fit standard PLC logic. Support leans on real production data, not generic checklists—remote diagnostics flag voltage drift or ink viscosity trends before they become downtime. Finally, you see proof in your exact industry: a beverage plant gets case studies from beverage plants, not generic industrial claims. That specificity tells you the vendor understands your line speeds, washdown demands, and compliance codes well before installation.
Contact Us
Contact Person: Jacky
Email: [email protected]
Tel/WhatsApp: 086 15000607053
Website: https://www.danmajet.com